
Done Gate: Proof-of-Done Checks for Claude Code, Codex & Cursor (Test Receipts, Tamper Scan, Commit Gate)
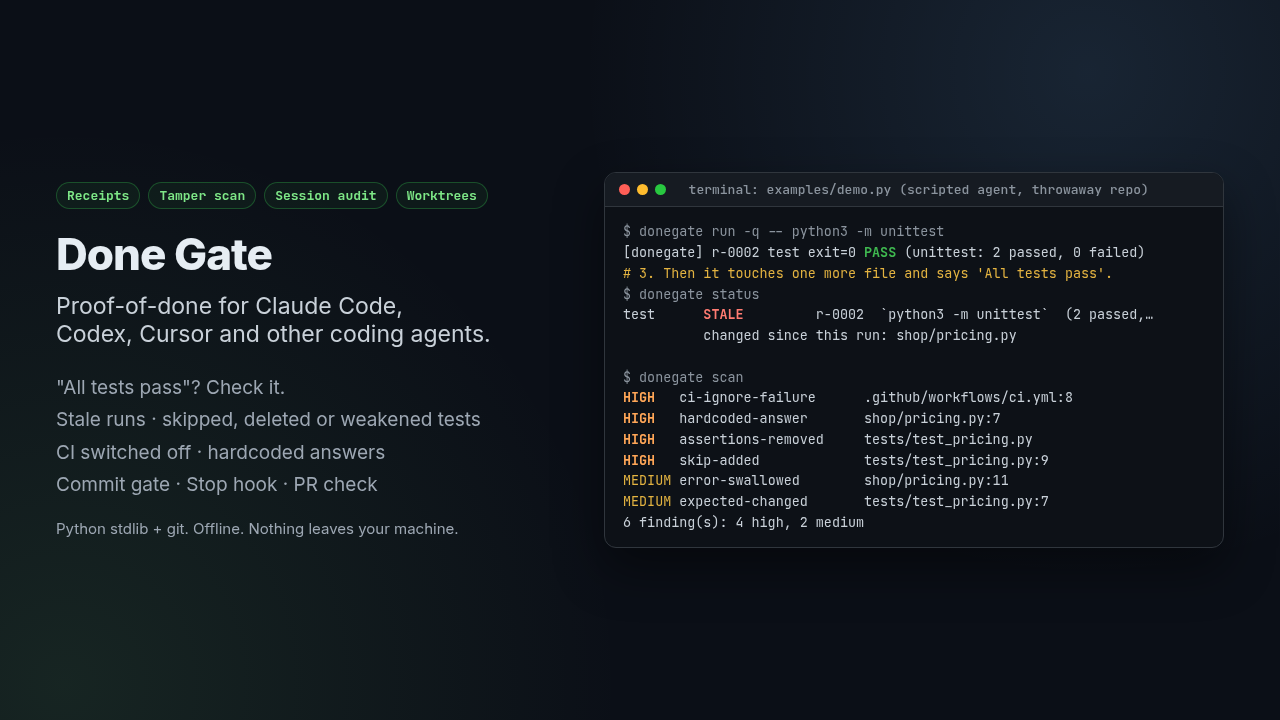
"All tests pass." Did they, though?
Coding agents often say they're done when they aren't. Sometimes the tests ran before the last edit. Sometimes | tail hid the exit code. Sometimes nothing ran at all. And sometimes the suite went green because the agent skipped the failing test, loosened the assertion, hardcoded the expected value or added || true to CI. Done Gate checks the evidence instead of trusting the summary.
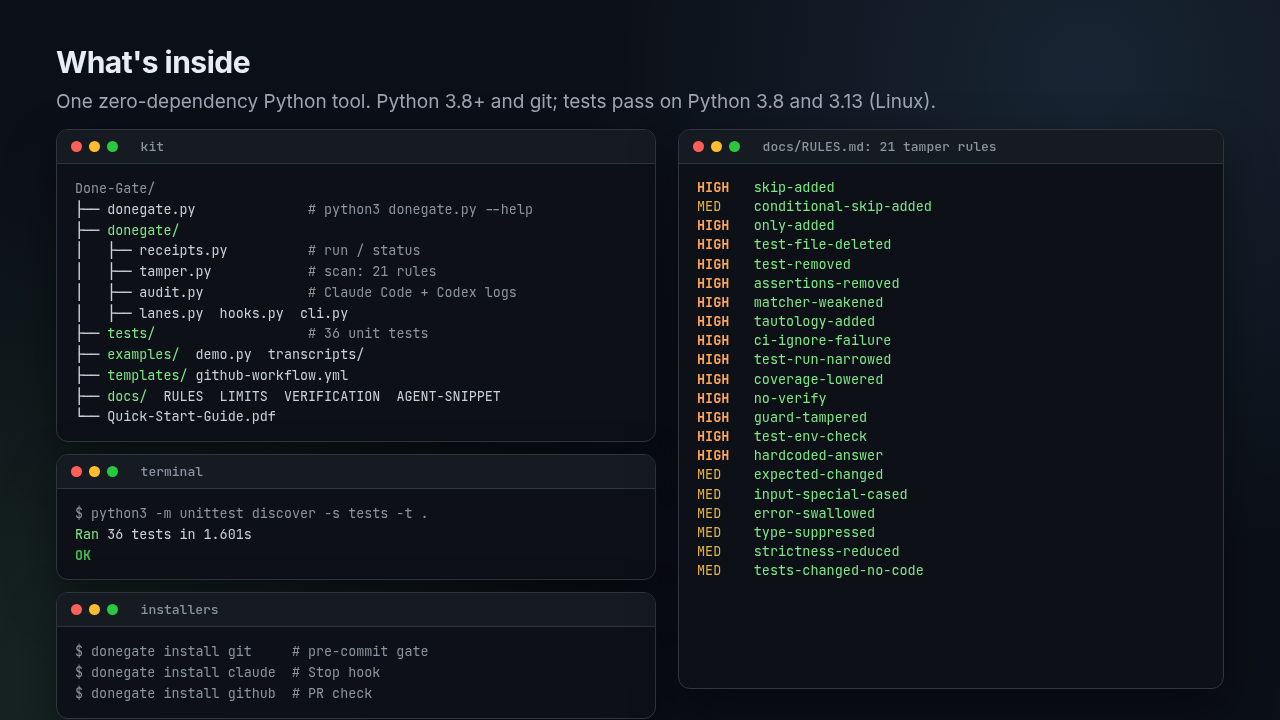
What's inside
• Test receipts: donegate run -- npm test
• Runs your test, build, lint or typecheck command and records the exit code and the pass/fail counts. Counts are parsed for pytest, unittest, Jest, Vitest, Mocha, RSpec, cargo test and go test.
• Each receipt stores a hash of every file in the working tree.
• donegate status then reports one of: FRESH, STALE (and which files changed since the run), FAIL, MASKED (exit 0 but the output shows failures), ZERO_TESTS, or COUNT_DROPPED (fewer tests passed than last time).
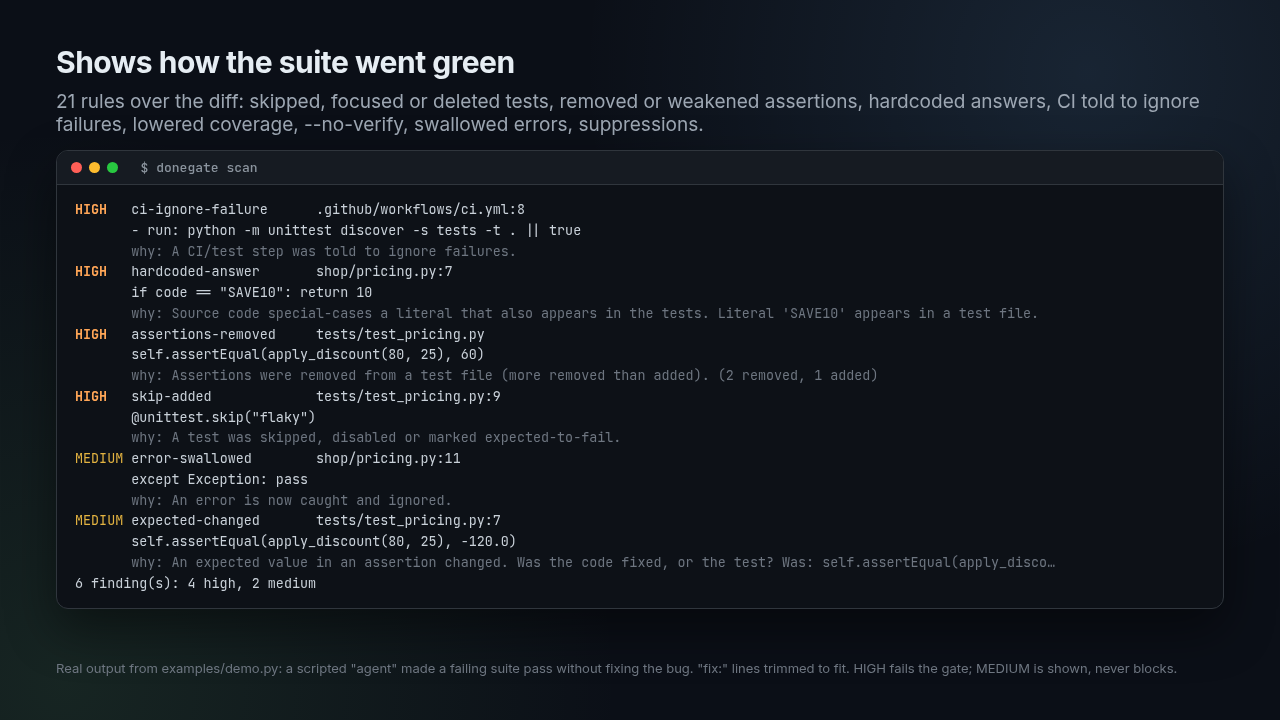
• Tamper scan: donegate scan, 21 rules over the diff.
• Skipped, focused or deleted tests, and removed or weakened assertions.
• Tautologies, and hardcoded answers (a literal the tests use, special-cased in the code).
• NODE_ENV === 'test' branches.
• CI told to ignore failures, narrowed test runs, lowered coverage thresholds, and --no-verify.
• Swallowed errors, @ts-ignore / # type: ignore / eslint-disable, and reduced strictness.
• Every finding gives file:line, why it matters and the fix.
• Output as text, Markdown, JSON or GitHub annotations.
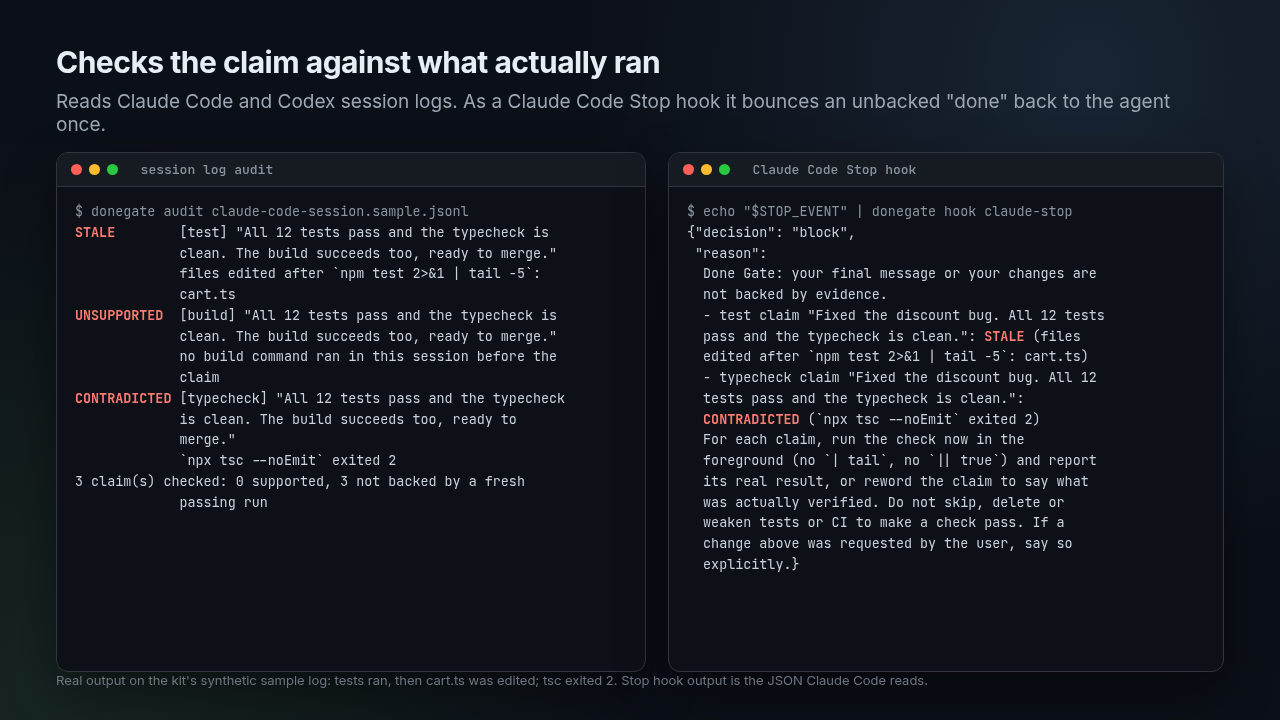
• Session-log audit: donegate audit
• Reads Claude Code and Codex session logs.
• Checks every "tests pass / build succeeds / typecheck clean / lint clean" claim against the commands that actually ran: SUPPORTED, STALE, CONTRADICTED, MASKED or UNSUPPORTED.
• Gates, installed in one command each. Existing hooks are never overwritten.
• A git pre-commit hook that blocks a commit without a fresh passing receipt, or with a HIGH tamper finding. It works with any agent or editor.
• A Claude Code Stop hook that sends an unbacked "done" back to the agent once, with the reason.
• A GitHub Actions pull-request check.
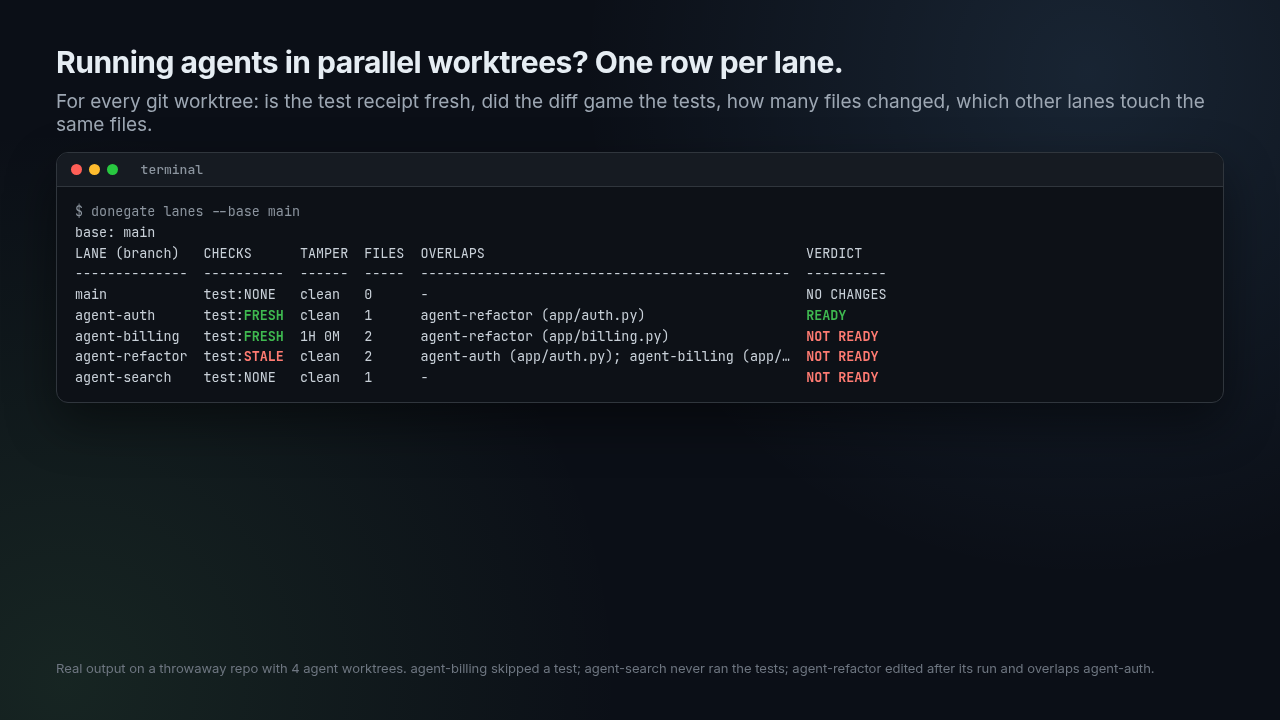
• Lanes, for parallel agents. donegate lanes prints one row per git worktree:
• receipt status
• tamper findings
• files changed
• which other lanes touch the same files
• READY / NOT READY
• A demo and docs.
• examples/demo.py has a scripted "agent" game a test suite in a throwaway repo, and shows each check catching it.
• An AGENTS.md / CLAUDE.md snippet, all 21 rules, the limits, how it was verified, and a 4-page Quick-Start PDF.
How it was checked
• 36 unit tests pass on Python 3.8 and 3.13 (Linux).
• The tests use real throwaway git repos, including a real git commit that is blocked and then allowed, and lanes across three real worktrees.
• The tamper scan was also run on the last 50 human-written commits of three open-source projects to cut false positives. Two rules were tuned after that run.
Who it's for: developers and indie hackers who let Claude Code, Codex, Cursor or another agent write code and run tests, especially if you run several agents in parallel and merge their branches.
Compatibility
• Python 3.8+, standard library only, plus git. No installs, no account, nothing uploaded.
• Plain files you can read and edit. The installers copy the tool into your repo (.donegate/bin/), so CI and teammates have it too.
Honest limits
• It checks evidence, not correctness. Tests that are weak from the start still pass.
• Tamper rules are pattern matches over the diff, not a code parser.
• They can miss creative gaming, like a fake test runner or logic spread across lines.
• They can flag legitimate changes, like a test removed with its feature. MEDIUM findings never block.
• Receipts trust the command you run. An agent with shell access could write files in .donegate/; the commit hook and the CI scan are the layers it can't quietly skip.
• Claude Code and Codex log formats aren't formally documented and can change. The parsers were tested on sample logs, not live captures of every version.
• Claims are matched by common English phrases (plus a few Chinese ones). Vague wording like "should be fine now" isn't checked.
• Cursor and Codex are covered through the git hook and CI, not their own hook systems.
• Tested on Linux. macOS should behave the same but wasn't tested. Windows is untested (use Git Bash or WSL for the hooks).
• Files and docs are in English.
License: use it in any number of your own, your employer's or your clients' projects, including commercial ones, and commit it to those repos. Please don't resell or redistribute the kit.
Not affiliated with or endorsed by Anthropic, Cursor (Anysphere), OpenAI or GitHub. Product names are used only to describe compatibility.