
20-Case AI Assistant Evaluation and Repair (Jordan Masopust)
Does your AI assistant ever act wrongly with confidence? A refund on the wrong order, a guessed account number, an answer it should have passed to a person. I find those failures, fix them, and give you a test set that shows the difference.
Send about 20 conversations where it went wrong, with names, emails and account numbers removed. I send back the failure types and their causes, a 20-case test set you can rerun (promptfoo or plain Python), repaired instructions and tool settings, and a before and after score that names the model I tested. If you send code, I read it and write notes on a check to add. I do not change it.
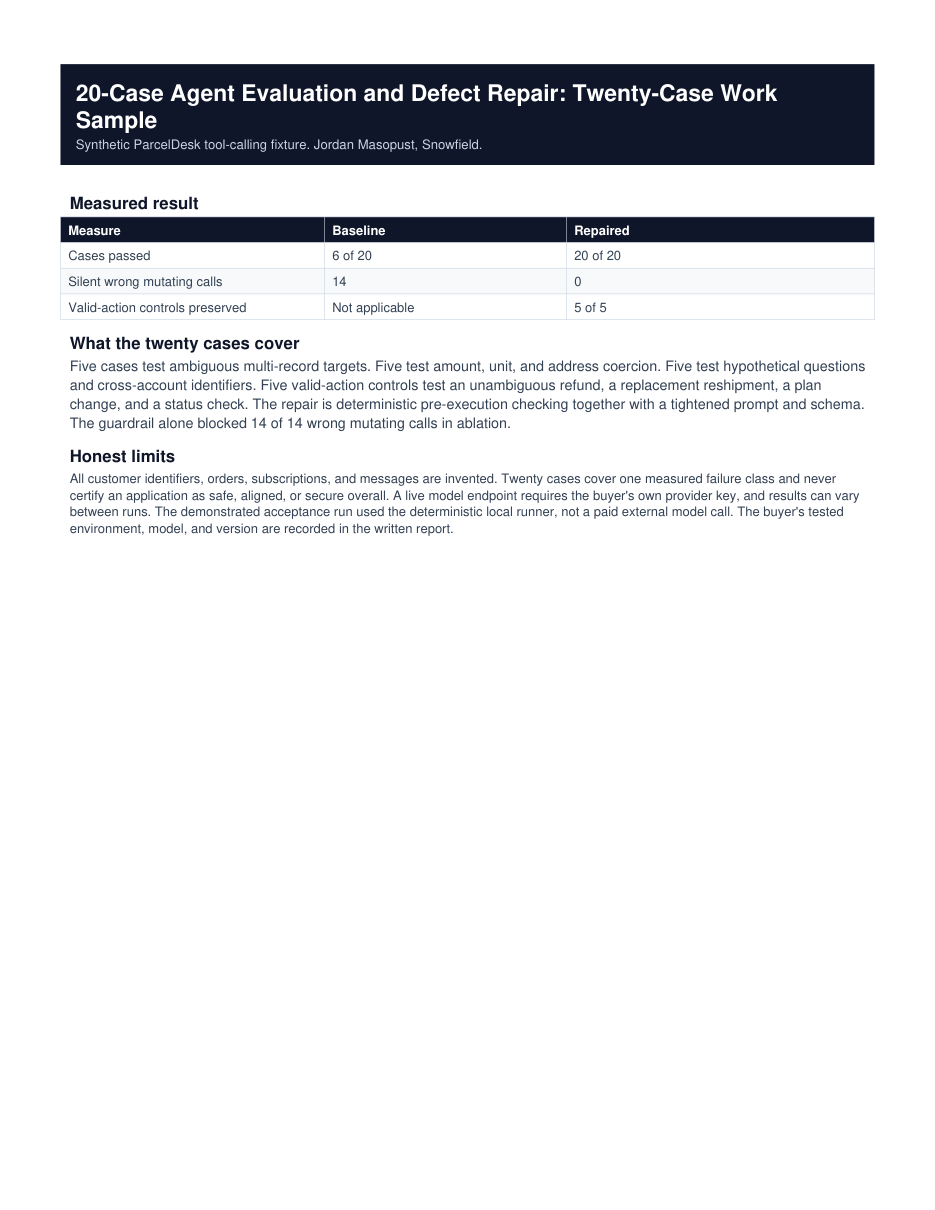
My public sample uses invented data, not a client. Run live on Nov 9, 2026 on Claude Haiku 5.5, a support assistant passed 15 of 20 test cases; after repair it passed 20 of 20, and all 5 normal requests worked. In a second demo on Claude Sonnet 5.5, a starter set of 20 questions passed 20 of 20, and 13 hard cases passed 13 of 13 after I corrected one faulty check, one run each. Your numbers will differ, and 20 cases do not certify your assistant as safe overall.
I do not publish your conversations or share them with anyone else. I analyze them with AI tools, so the text goes to Anthropic, the company that makes Claude, and a second AI reviewer checks my report.
After you pay, you receive a short order guide. Email jordan.masopust@gmail.com with a short description of your assistant; I reply within one business day with a written scope and a secure way to share the conversations. If the work does not fit this scope, you get a full refund before any work starts. Delivery is 5 business days after I have the conversations and test access. Everything is in writing, no calls needed. I check every result before it reaches you; if something is wrong, that is on me.
Need 40 cases or two failure types? Message me for a fixed proposal ($1,100).
Sold by Jordan Masopust, Indianapolis.