
Local AI Stack Kit: Qwen3.6-35B-A3B on one RTX 3090
You have a 24 GB card and want a local model that can drive a coding agent. This kit is the setup we run on our own test box: one RTX 3090, llama.cpp and Qwen3.6-35B-A3B. The commands are the ones we ran, and every number comes from our benchmark logs.
What's in the zip
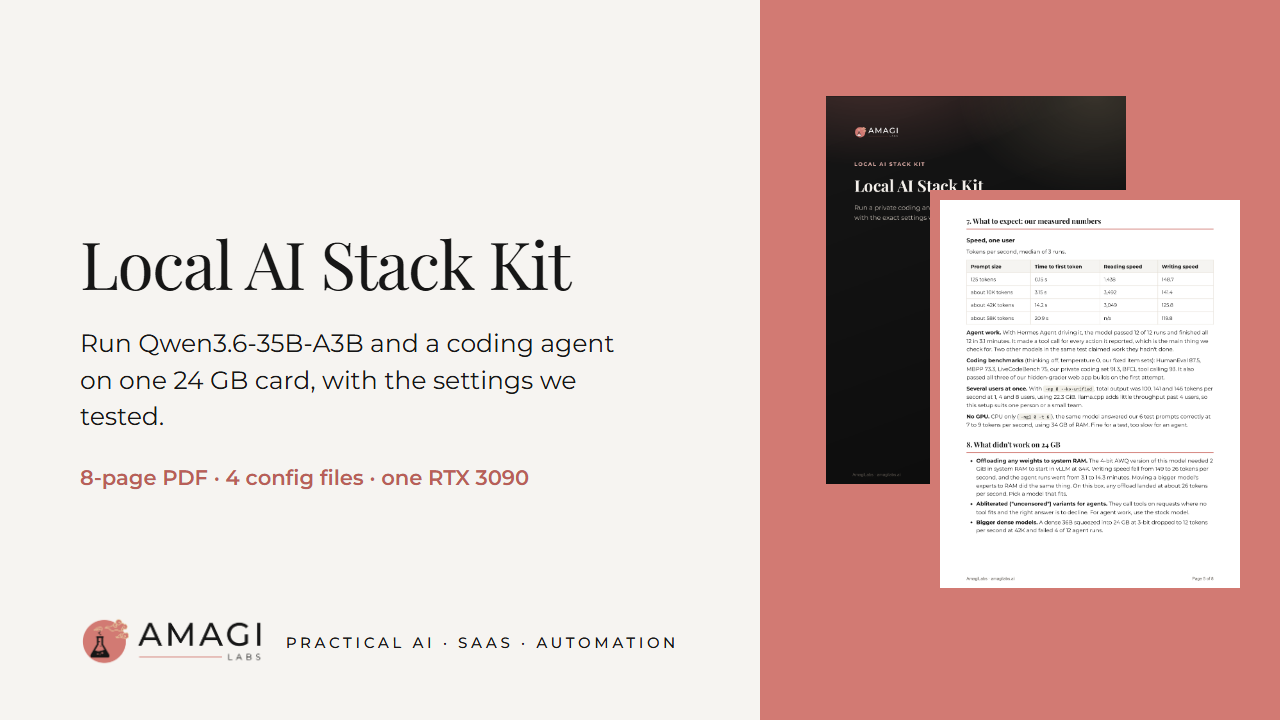
- An 8-page PDF guide: building llama.cpp, the model file to download, the power cap, every server flag and what it does, and the two request settings that change results (thinking off, forced tool calls).
- serve-qwen36.sh: starts the server with our tested settings. It won't start if another process is already using the GPU, and AGENT=1 switches to the sampling from our coding-agent bench.
- smoke_test.sh: checks that the server answers, that thinking is off and that a forced tool call comes back.
- goose-local.sh and opencode.json: point the goose and opencode coding agents at your local server, with telemetry, auto-update and sharing turned off.
- MIT license on our scripts.
What we measured on our box
- About 149 tokens per second writing speed on short prompts, and 126 at 42,000 tokens of context
- 64K context with a full-precision cache, using 21.9 GiB of the card's 24
- 12 of 12 agent runs passed with Hermes Agent driving the model
- goose passed 5 of 5 small coding tasks in a real Python repo with no nudges; opencode passed 5 of 5 with one nudge
- All of it ran on the one card, with nothing sent to a cloud API
- On 2026-10-29 we ran the scripts in this zip the way a buyer would. The smoke test passed, and goose-local.sh fixed a failing test in 22 seconds with a one-line change.
What didn't work on 24 GB
The guide covers what failed on 24 GB: offloading weights to system RAM (speed fell to about 26 tokens per second), abliterated variants for agent work, and bigger dense models squeezed to 3-bit. It also lists two backup models we ran on the same harness, Gemma 4 26B-A4B and Ornith-1.5-35B-A3B, with their numbers.
Before you buy
- You need a 24 GB NVIDIA card, the NVIDIA driver and the CUDA toolkit. We tested on one RTX 3090 running Ubuntu 24.04.
- The kit doesn't include llama.cpp, the model or the agents. You download them from their publishers: llama.cpp is MIT, Qwen3.6 is Apache-2.0, goose is Apache-2.0 and opencode is MIT.
- These are our results on one card with one quant per model. Your speeds will differ with a different card, driver, cooling or llama.cpp build. Nothing here is a performance guarantee.
How it was made
Written with AI help (Claude). We ran every script in the zip on our own test box before release.
Refunds
All sales are final. You get this digital download right away, so we don't give cash refunds. If a file won't open or the product doesn't match this page, email us within 7 days of purchase. We'll fix it or send a replacement. If we can't, you'll get store credit for the full price.
EU and UK buyers: you'd normally have 14 days to withdraw from this purchase. You lose that right once your download or access starts, because you ask for immediate access at checkout. If the product is faulty or not as described, the 7-day limit doesn't apply to you. If we can't fix it, you can choose a refund instead of store credit.
Nothing in this policy limits your rights under the law where you live. You can ask us for a written copy of this policy at any time.
Format: one zip with the PDF guide, the configs/ folder and the LICENSE file.