
CLEAN VOICE DATA WITH NO COMPLIANCE RISK




Dataset Provenance & Vendor Profile
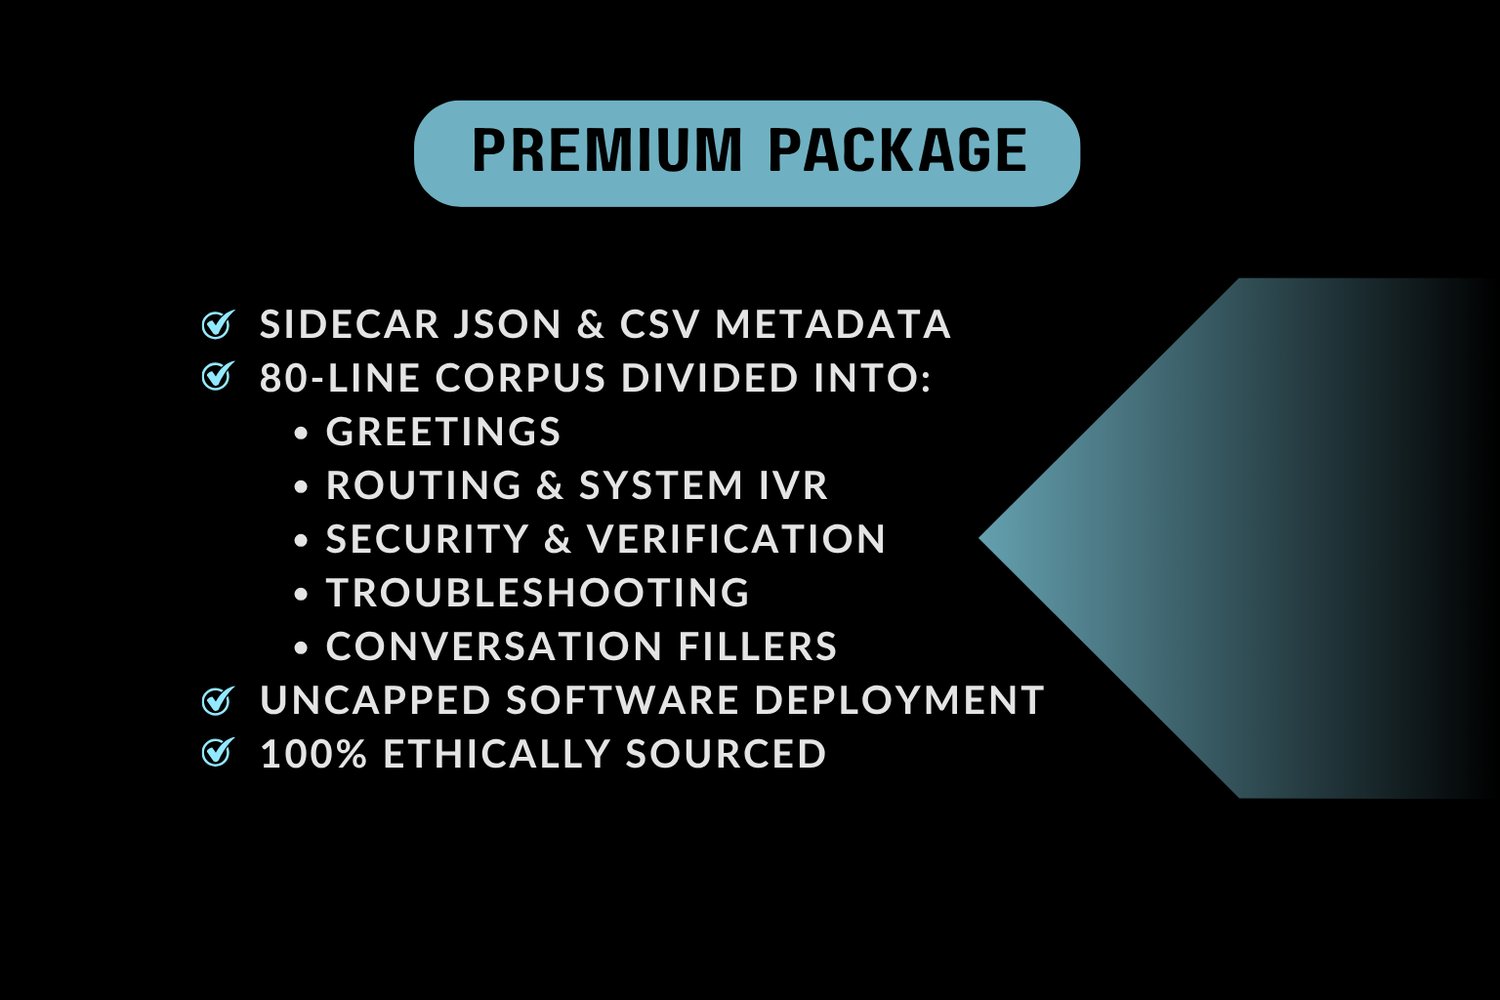
All repositories are curated and engineered by an AI-trained vocal professional with a background in machine-learning data operations, audio engineering, and voice synthesis. Having built datasets directly for major AI corporations, the vendor structures all assets to meet the prerequisites of modern Text-to-Speech (TTS) and voice-cloning pipelines.
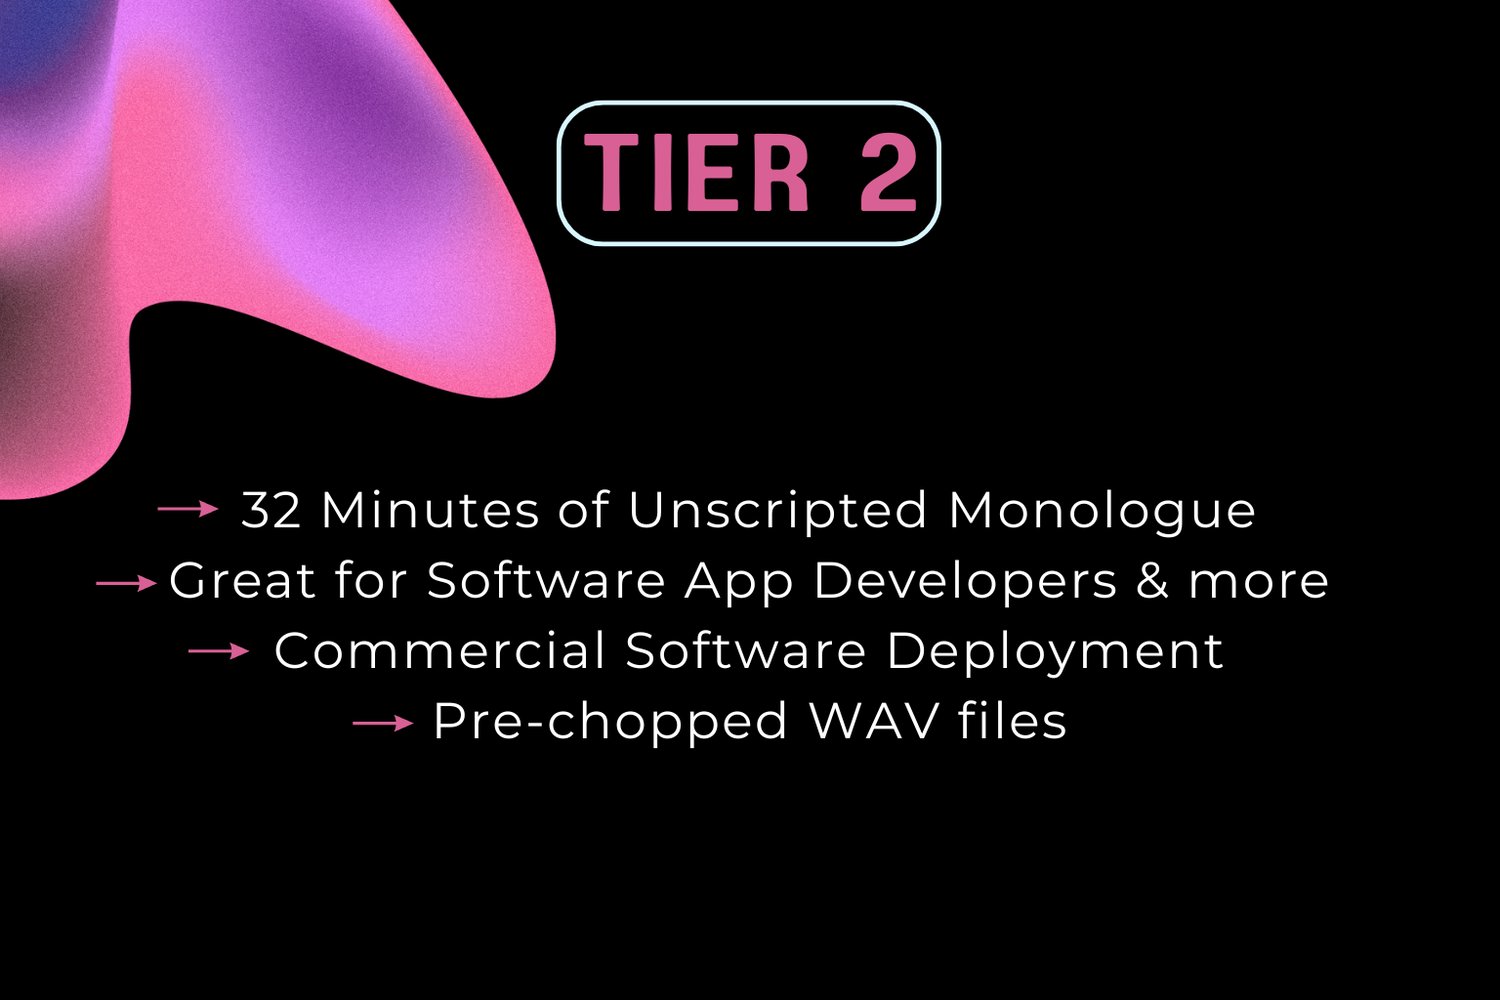
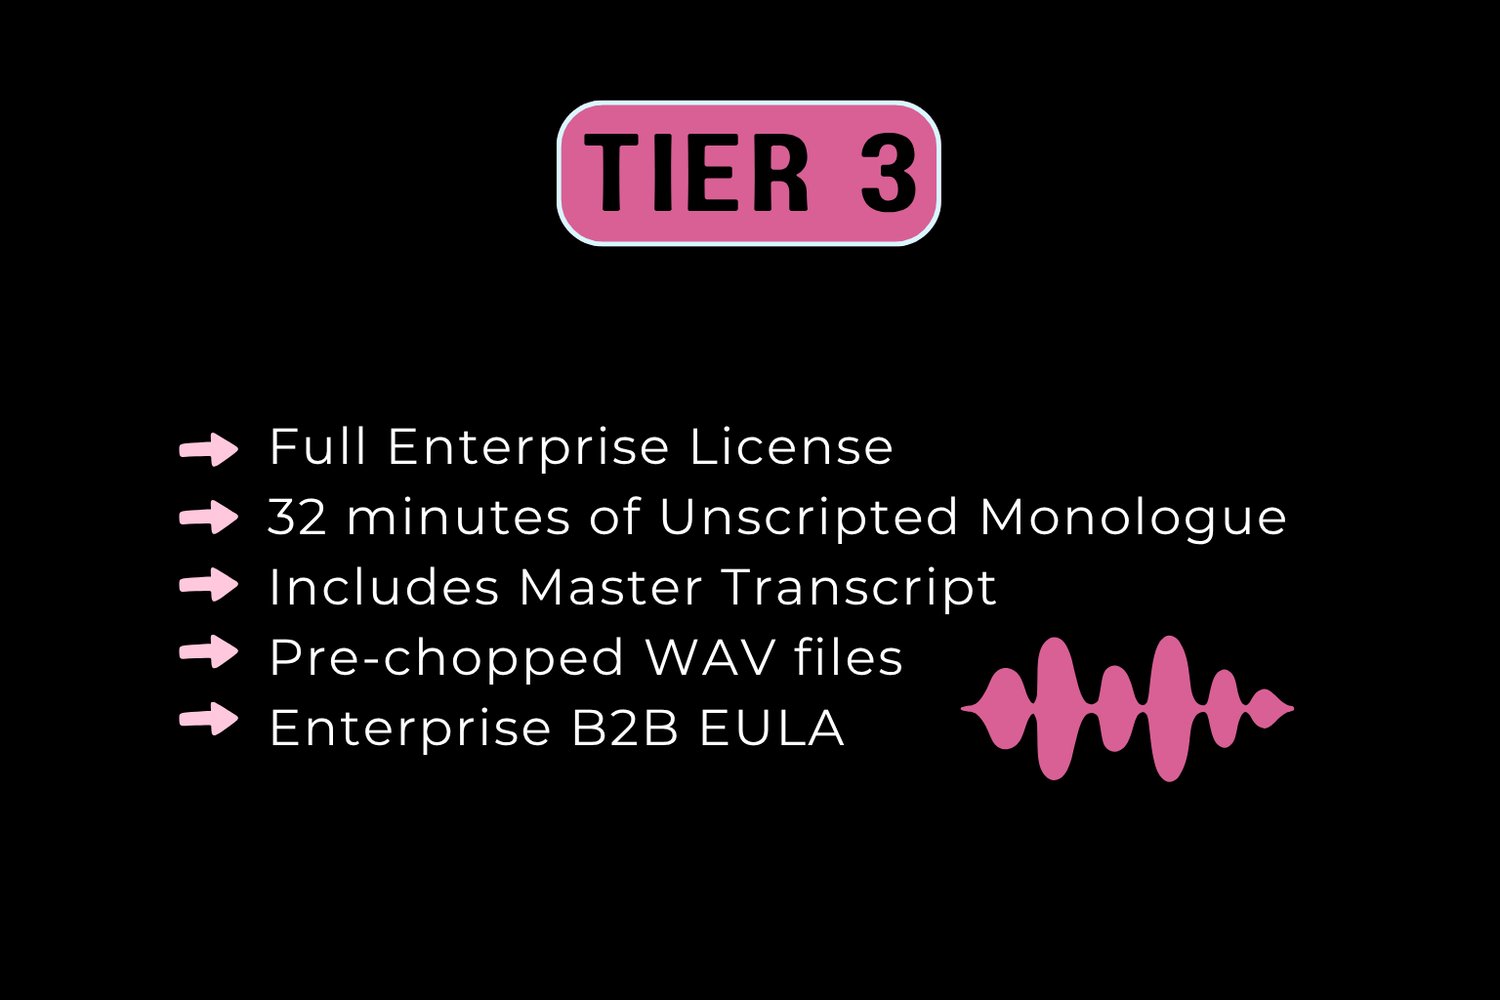
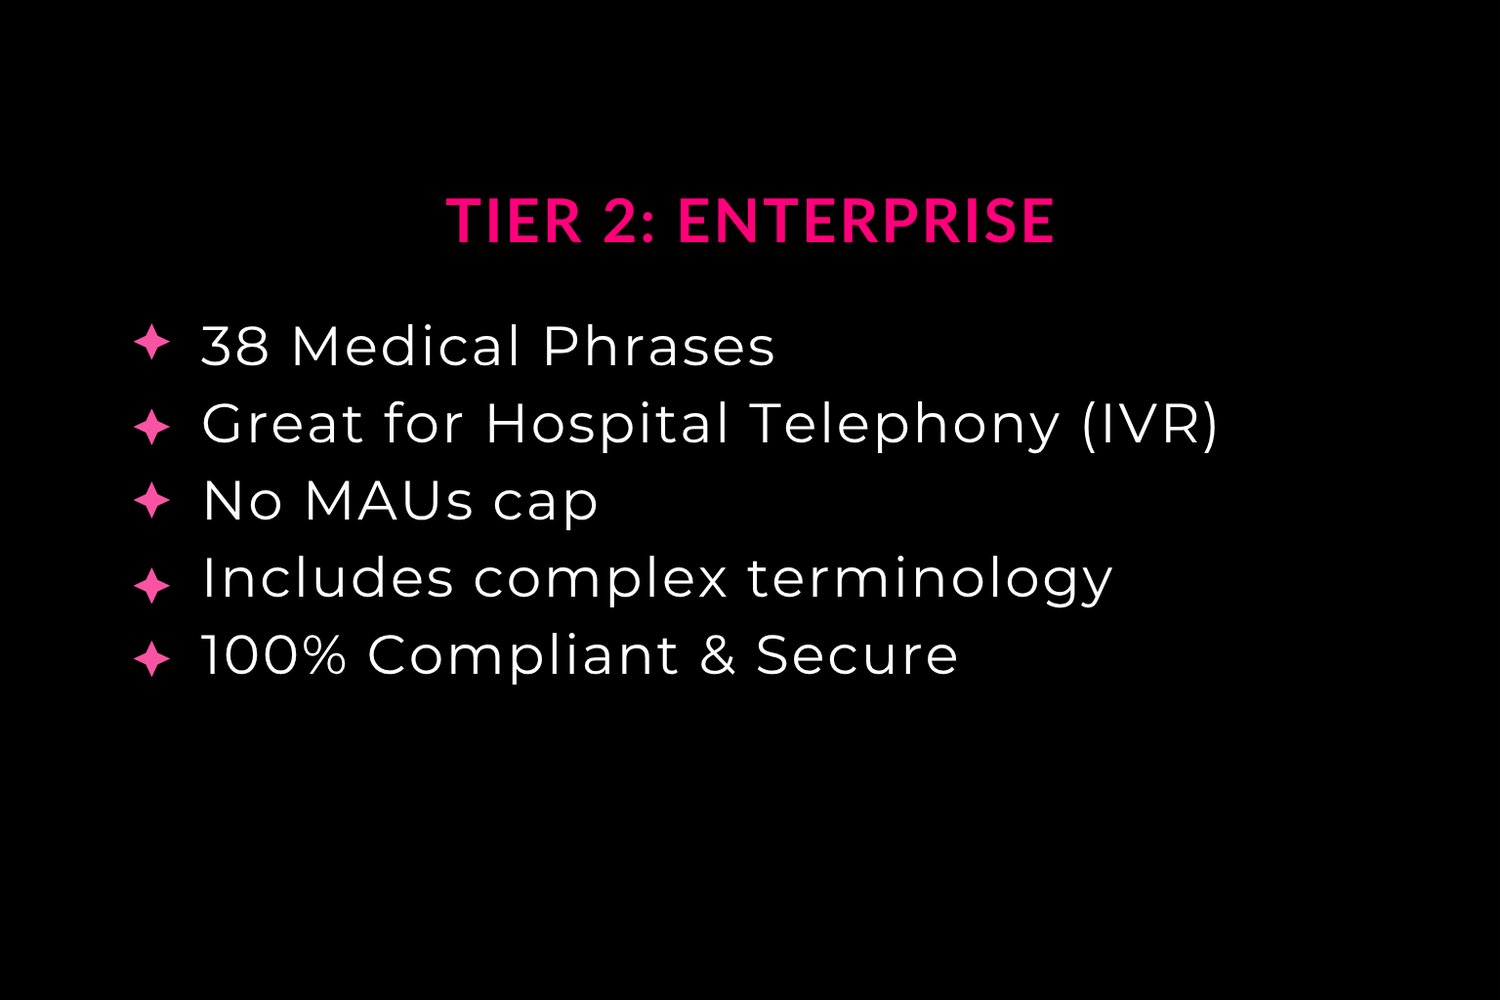
- Acoustic Standards: High-fidelity, 16-bit Mono WAV files at 44.1kHz. Zero-echo, noise-gated studio captures.
- Legal Compliance: 100% Opt-In Human Data. Explicitly contractually backed for machine learning model training, AI call-bots, and commercial synthesis applications. No scraped data. GDPR/CCPA safe.

100% HUMAN DATA