
North American Female Vocal Datasets [Single-Source]
Skip the headache of web scraping and tedious audio cleaning. Marie DeVox supplies high-fidelity, hand-annotated vocal datasets engineered specifically for TTS, ASR, IVR, and commercial voice fine-tuning.
Each file features crystal-clear audio, standardized metadata, and 100% verified legal provenance so you can train and deploy with complete confidence!
Conversational NLU & Utterance Taxonomies
[Coming Soon]
Supercharge your language models with structured, multi-intent conversational text datasets. Designed for intent mapping, entity recognition, and natural spoken-dialogue flows, these datasets give your conversational AI the linguistic depth it needs to handle complex user inputs. Built to integrate directly into your preprocessing pipeline for faster model deployment.
Voice Bot UX & Escalation Blueprints
[Coming Soon]
Eliminate frustrating customer loops and deadlock fallbacks with plug-and-play VUI design frameworks. Built for prompt engineers and product managers who want to deliver smooth, zero-resistance voice experiences.
Zero Middlemen, 100% Compliant
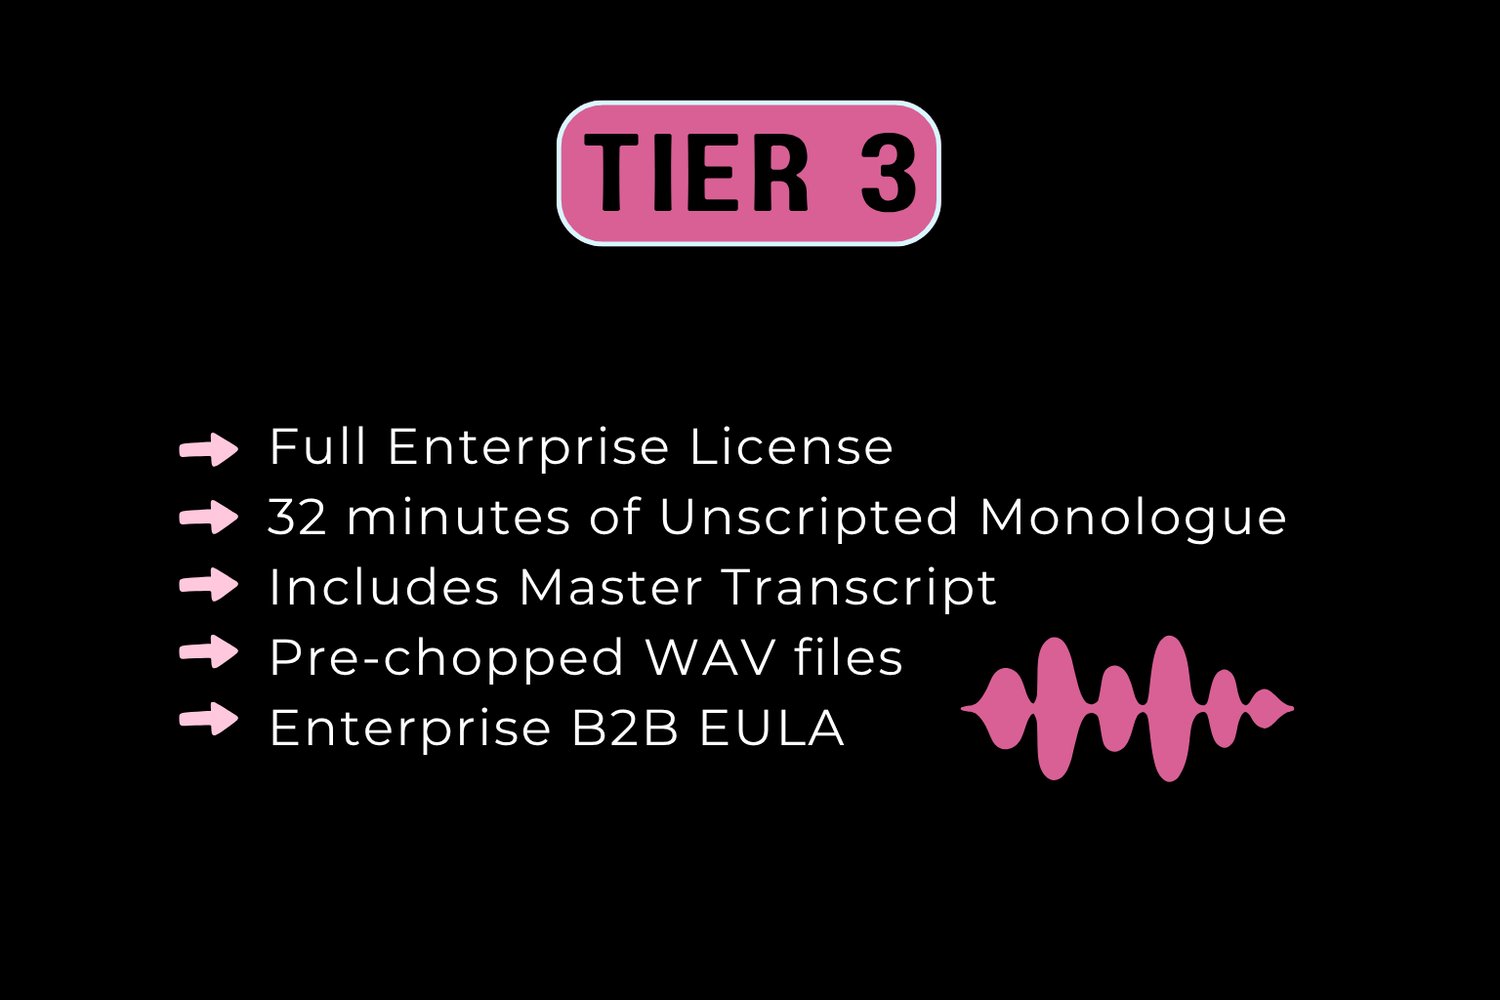
With every asset personally recorded, produced, and owned by Marie DeVox, your team never has to worry about third-party copyright liabilities or middleman licensing issues. Each purchase includes clear data provenance and flexible commercial rights, giving you absolute compliance safety for production and enterprise use.
PRODUCTS

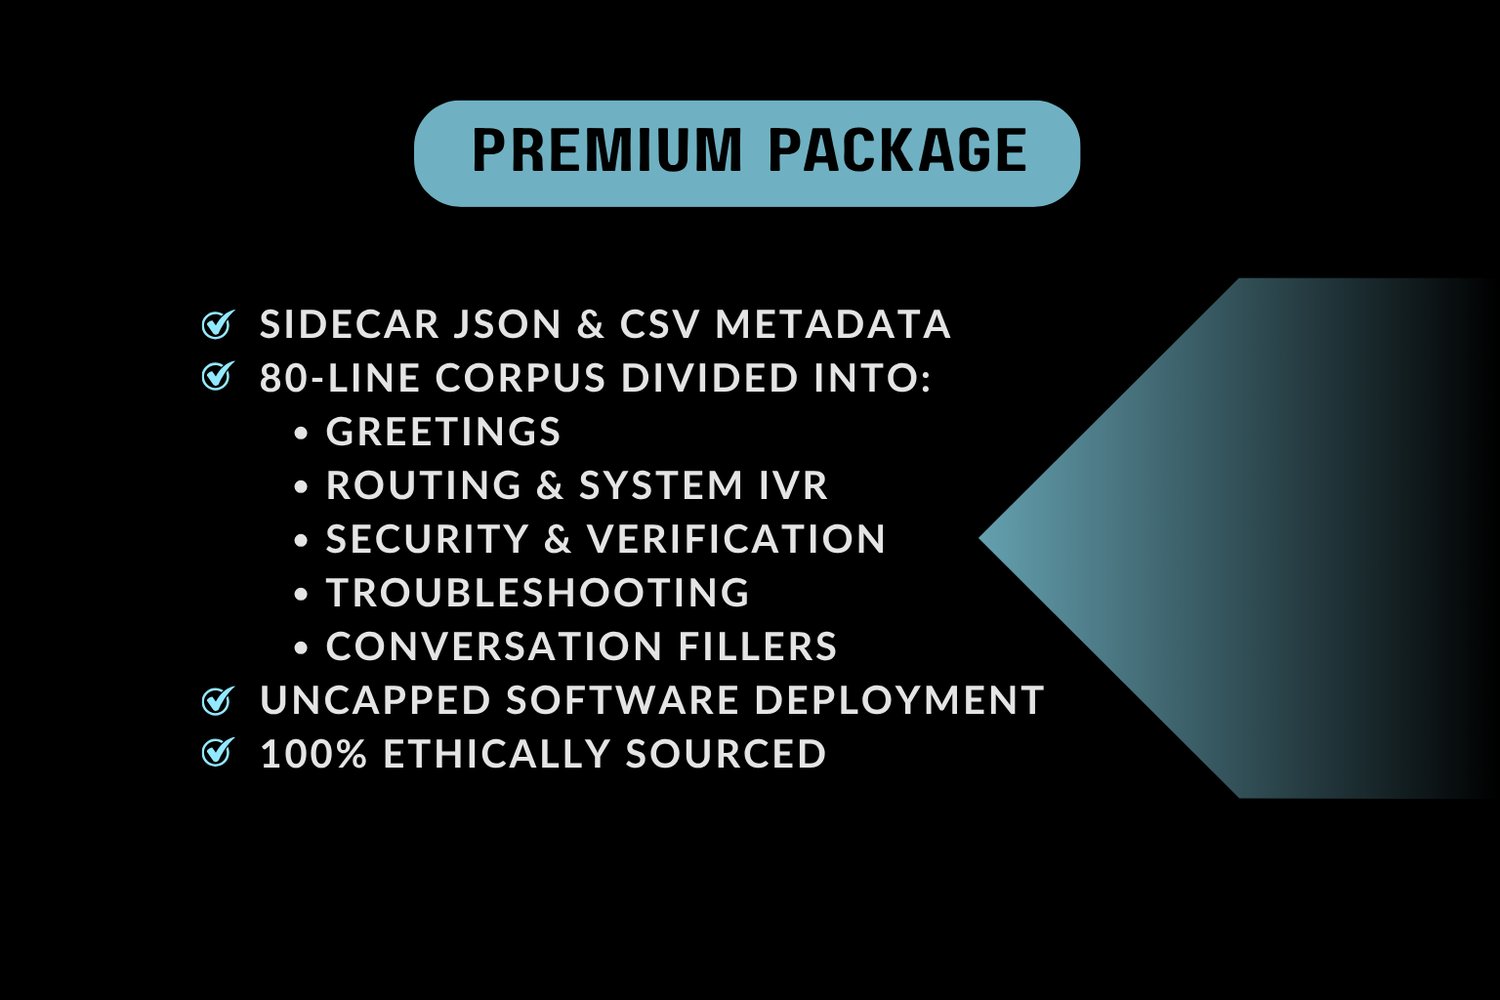
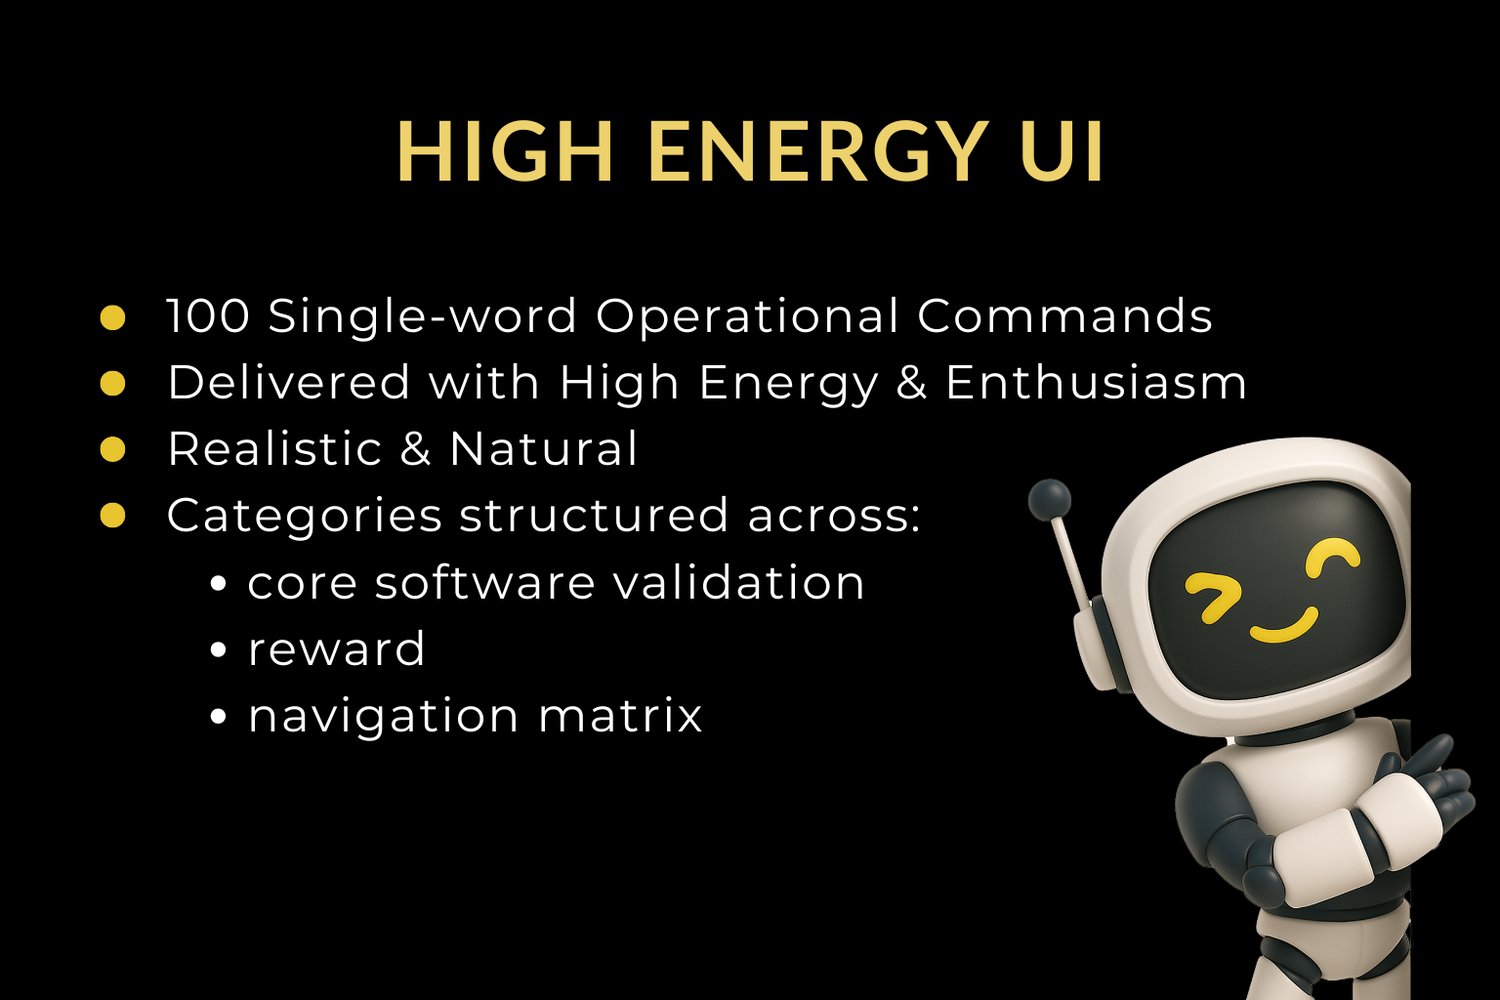
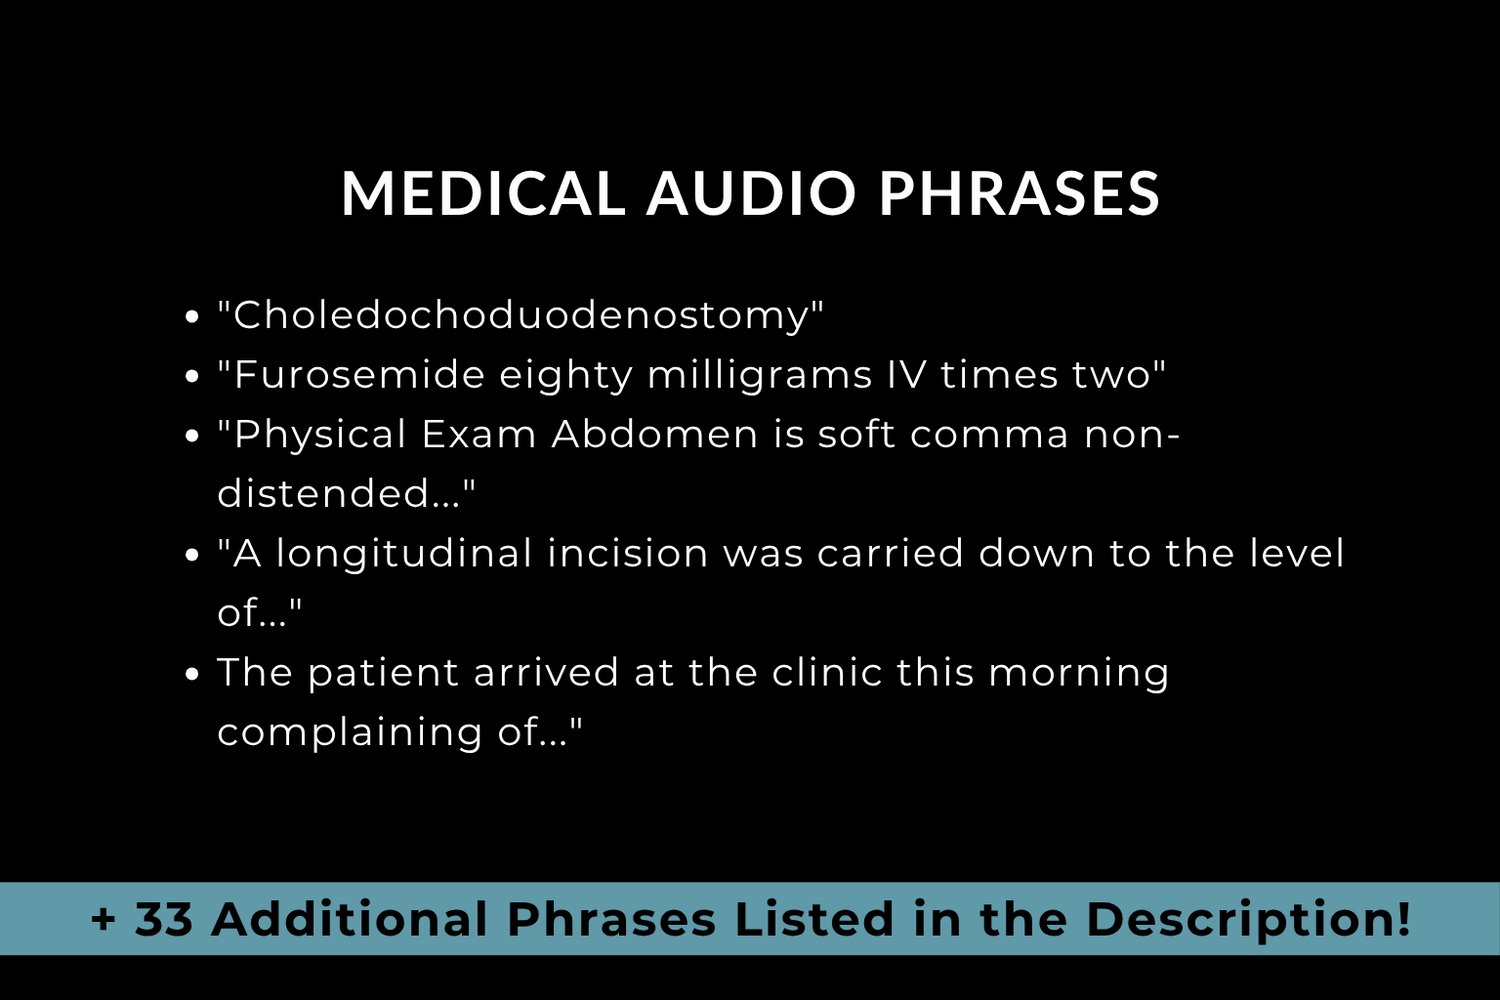
Dataset Provenance & Vendor Profile
All repositories are curated and engineered by an AI-trained vocal professional with a background in machine-learning data operations, audio engineering, and voice synthesis. Having built datasets directly for major AI corporations, the vendor structures all assets to meet the prerequisites of modern Text-to-Speech (TTS) and voice-cloning pipelines.
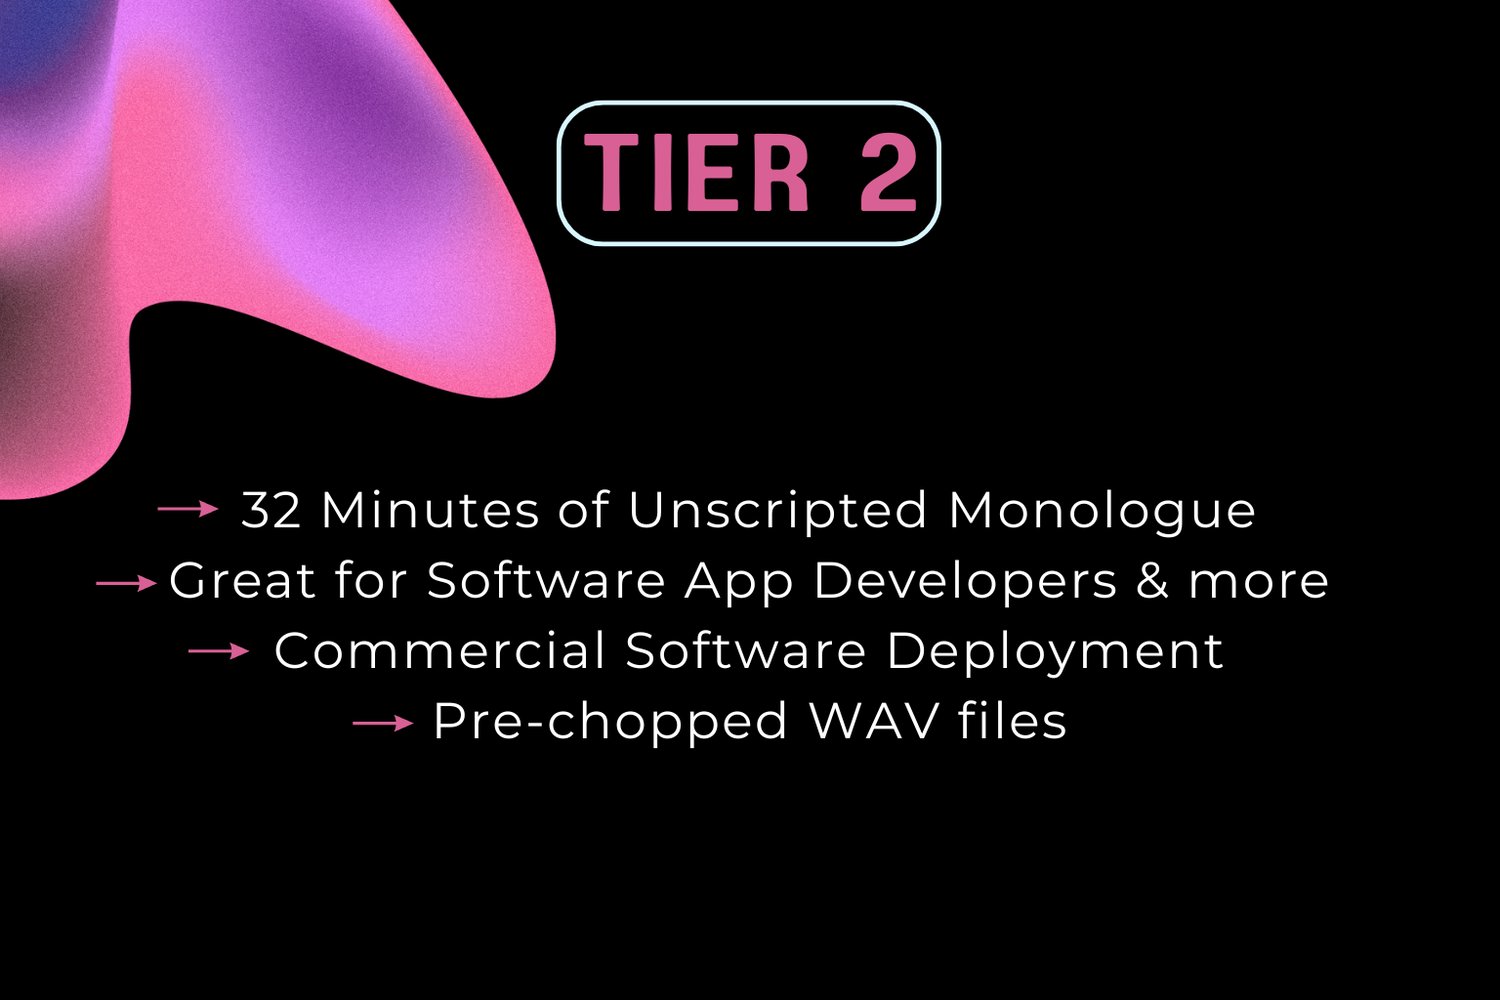
- Acoustic Standards: High-fidelity, 16-bit Mono WAV files at 44.1kHz. Zero-echo, noise-gated studio captures.
- Legal Compliance: 100% Opt-In Human Data. Explicitly contractually backed for machine learning model training, AI call-bots, and commercial synthesis applications. No scraped data. GDPR/CCPA safe.
100% HUMAN DATA